
Table of contents of the article:
There's a common paradox among those working in web performance optimization: on the one hand, they rightly recognize the importance of real user data, but on the other, they often come to the conclusion that the only data that matters is CrUX data and that, consequently, lab data can be safely ignored.
It is a seemingly logical approach, but technically incomplete.
If a site passes the Core Web Vitals based on real-world data collected by Chrome, why should we care about a Lighthouse test that perhaps returns a slower Largest Contentful Paint, a high Total Blocking Time, or a less-than-stellar Performance score?
The answer is that CrUX and LABS don't measure exactly the same thing, and more importantly, they don't serve the same purpose.
Field data tells us what actually happened to users who visited the site. Lab data, on the other hand, allows us to understand how that page behaves under controlled, repeatable, and potentially more critical conditions.
Ignoring either one means voluntarily giving up an important piece of information.
The false myth: "If the CrUX data is good, the site is fast"
The reasoning we often hear goes something like this: Google evaluates Core Web Vitals using real data, so the only thing that matters is passing the CrUX evaluation. If PageSpeed Insights shows green field data, what happens in the Lighthouse section becomes secondary or even irrelevant.
The problem arises from the fact that two different concepts are confused: the measurement of what has happened and the diagnosis of what might happen.
The Chrome User Experience Report, commonly called CrUX, collects data from the real experiences of eligible Chrome users and aggregates it by URL or by origin.
If you want to learn more about the differences between metrics and measurement methods, we also recommend our in-depth study on Core Web Vitals and CrUX data.
There is one key point to note, however: CrUX is not simply an average of site performance.
The 75th percentile is used to evaluate Core Web Vitals . In simple terms, this means that for a given metric, at least 75% of recorded experiences must have a value equal to or better than the reported one.
Currently the three Core Web Vitals metrics are:
- LCP – Largest Contentful Paint, with a “Good” threshold of up to 2,5 seconds;
- INP – Interaction to Next Paint, with a “Good” threshold of up to 200 milliseconds;
- CLS – Cumulative Layout Shift, with a “Good” threshold of up to 0,1.
This system is much more meaningful than a simple average because it limits the effect of outliers. However, precisely because we're talking about a statistical distribution, a good CrUX value doesn't automatically mean that every user is browsing quickly.
The population problem we are observing
Let's take a deliberately simple example.
Let's imagine an Italian website whose traffic comes overwhelmingly from Milan, Rome, and other major cities. Let's also assume that a large portion of these visitors use recent smartphones connected via fiber optics, fast Wi-Fi, or 5G mobile networks with low latency.
That will be the predominant population within the collected experiences.
If 90% of users are browsing under particularly favorable conditions, it is perfectly possible to obtain excellent CrUX values even if the page, from an absolute point of view, is anything but light.
Now imagine opening the exact same site from a rural or mountainous area of Sardinia, the Apennines, or any other region where mobile connectivity is less efficient, perhaps via a congested 4G network with higher latency and a low-to-mid-range smartphone.
The experience can become completely different.
An 800 KB hero image, four fonts loaded from external domains, 700 KB of JavaScript, an advertising platform, a consent management script, a tracking system, and various third-party widgets can be nearly invisible on a very fast connection, but become extremely noticeable as latency, download time, and device processing power increase.
The site didn't suddenly become heavier; it was heavier before. The connection quality and hardware prevalent in the real sample were simply mitigating its effects.
Naturally, the geographic example helps illustrate the point: the differences don't just depend on the city or region. The device, CPU power, network used, latency, device load, cache, browser, user behavior, and numerous other factors also play a role.
CrUX describes your users, not all possible users
This is probably the most important point of the whole issue.
CrUX data is representative of actual experiences collected for that site, not of every possible browsing condition.
And that's exactly how it should be.
The job of field data is to tell us what's happening in the real world. It would be wrong to expect them to do anything different.
The problem arises when we turn this feature into an absolute conclusion and say: “CrUX is green, therefore the site is fast and I don’t have to investigate further”.
The correct sentence should be:
“CrUX is green, meaning at least 75% of the experiences collected for the metrics considered currently fall within the Good thresholds.”
That's a very different statement.
By the way, PageSpeed Insights displays CrUX data for a window spanning the last 28 days. This means the field data inevitably has a historical component.
If we introduce a change today that significantly degrades a page's performance, LAB data can highlight it immediately. CrUX data, on the other hand, must gradually incorporate new user experiences.
Again, this isn't a flaw in CrUX. It's simply a consequence of how aggregated measurement over time works.
What are LABS data really used for?
The laboratory data answer a different question.
Instead of asking ourselves “how did our visitors actually navigate?”, they allow us to ask ourselves:
“How does this page behave if we eliminate some of the external variables and subject it to a reproducible scenario?”
Lighthouse, also used by PageSpeed Insights for the lab section, performs the analysis within a controlled environment.
This allows you to identify technical issues that might be difficult to spot by looking at the aggregate CrUX data alone: render-blocking resources, excessive JavaScript, long tasks on the main thread, oversized images, problems in the LCP element load chain, unnecessary network requests, unused CSS, third-party scripts, and numerous other issues.
The great advantage of the laboratory is repeatability.
If we make a change and want to understand whether we've improved or worsened page loading, we can run before-and-after tests under comparable conditions.
With real data, this immediacy is not possible, because users, networks, devices, and behaviors are constantly changing.
LABS does not mean “fake data”
Another common mistake is to associate the term “synthetic” or “lab” with something artificial and therefore meaningless.
It's true that a Lighthouse test can't perfectly represent the full range of real-world traffic . But that's not its purpose.
A car crash test doesn't reproduce every possible accident that will occur in the real world. Yet no one would conclude that, for this very reason, crash tests are useless.
Similarly, a laboratory benchmark allows us to put the system in a known condition and observe how it reacts.
If a site maintains excellent LCP, low JavaScript load, and a free main thread even under more severe conditions than those typically experienced by the majority of its users, we have built a site with greater performance headroom.
And it is precisely that margin that can make the difference when conditions change.
Performance headroom is what we often don't see in CrUX data
Let's take two sites that both show a CrUX LCP of 2 seconds.
The first is technically very optimized: quickly generated HTML, effective caching, properly compressed images, few critical resources, minimal JavaScript, and a server infrastructure with very low response times.
The second one reaches the same 2 seconds, thanks mainly to the fact that the audience is using mostly modern hardware and very fast connections. The page is several megabytes in size and requires a significant amount of JavaScript.
Looking solely at the CrUX number we might conclude that the two sites are equivalent.
From a performance engineering standpoint they are not at all.
The former requires little to continue functioning well even when conditions worsen. The latter has much less headroom and can degrade quickly when latency, network congestion, or CPU load increases.
The LAB data helps precisely make this margin visible.
What happens when LABS is red and CrUX is green?
This is probably the situation that generates the most discussion.
The site outperforms Core Web Vitals in the field but Lighthouse reports mediocre performance.
Is it necessary to intervene?
Not necessarily on any single warning, and certainly not by obsessively chasing a Lighthouse score of 100. The Performance Score should not become an end in itself.
However, it would be a grave mistake to ignore the report completely.
A significantly negative LAB figure may indicate that the site has little performance margin (and a lot of room for improvement) and that actual good performance depends, at least in part, on the favorable conditions of its users.
In this situation, it is worth understanding why the laboratory is reporting worse values.
If you encounter 2 MB of JavaScript, huge images, blocking requests, or an LCP that depends on a long string of resources, the fact that current users can compensate for these issues with fast connections and devices doesn't make them good practices.
And when LABS is green but CrUX is red?
The opposite situation is also possible.
Lighthouse returns excellent results, but actual data shows insufficient LCP, CLS, or INP.
In this case, the lab is telling us that, in the controlled scenario used by the test , the page behaves correctly. CrUX, on the other hand, is telling us that in the real world something is going wrong.
Elements that a single LAB upload cannot adequately represent may come into play: post-upload interactions, personalized content, cookie banners, advertising, scripts that only load under certain conditions, very slow devices, or actual user behavior.
For example, INP depends on actual interactions with the page. A simple synthetic loading process can't automatically reproduce all the actions thousands of users perform during their sessions.
In such cases, the CrUX data becomes the starting point for looking for a problem that the laboratory will then attempt to reproduce and diagnose.
The correct workflow is CrUX → LABS → optimization → CrUX
The real mistake is therefore trying to establish which of the two families of data is "the right one".
They are both correct because they answer different questions.
A sensible optimization workflow should use field data to identify the problem and assess its real-world impact, then use laboratory tools to understand the technical causes.
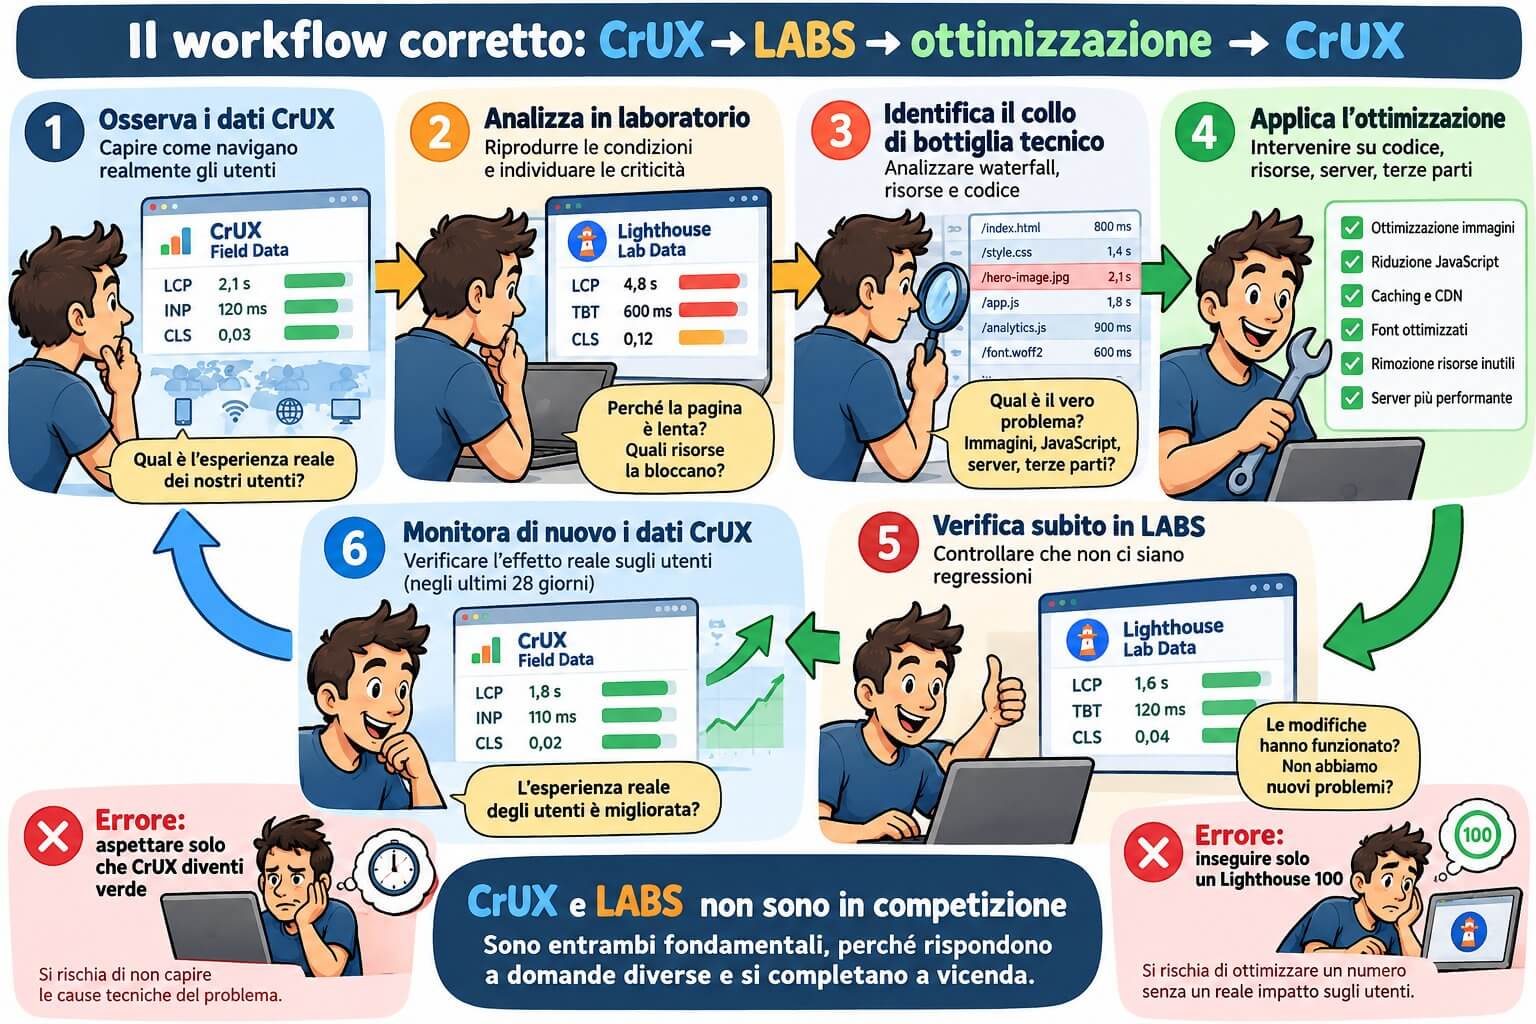
We can summarize the process this way:
- observe CrUX data and understand how users are actually navigating;
- analyze the page in the laboratory trying to reproduce the problematic conditions;
- identify the technical bottleneck;
- apply optimization;
- immediately check in LABS that no regressions have been introduced;
- subsequently monitor real data to verify the effect of the change on users.
This approach is much more rational than simply refreshing PageSpeed Insights and waiting for the CrUX tile to turn green or, at the other extreme, compulsively chasing a Lighthouse 100 without considering whether the intervention has a perceptible impact on users.
Let's not forget servers, hosting and Time To First Byte
There is another aspect that is particularly important for us, dealing with Linux hosting and systems on a daily basis.
Good web performance comes from the entire stack , not just frontend optimization.
The browser cannot actually start building a page that the server has not yet started delivering.
A WordPress application with inefficient SQL queries, overloaded PHP, no page caching, a poorly configured object cache, or an underpowered server infrastructure can significantly increase the time it takes to start receiving the HTML document.
TTFB is not one of the three Core Web Vitals per se , but a high server response time can propagate throughout the loading chain and contribute, in particular, to degrading the Largest Contentful Paint.
With users geographically close to the server and with excellent connections, some of these inefficiencies may be less noticeable. But that doesn't mean they don't exist.
When we run controlled tests under different network conditions and analyze waterfalls, TTFB, resource loading, and critical dependencies, we can better separate backend and frontend responsibilities.
And that's exactly what you need when the goal isn't just to get a green light, but to build a truly performance-robust site.
Curate LABS data to protect against attacks Core Web Vitals
Finally, there is a less discussed but interesting aspect precisely because it demonstrates how dangerous it is to design a site relying exclusively on the average conditions of its users: the possibility that the composition of real traffic may suddenly change, even in a non-spontaneous way.
In theory, in fact, a site that displays excellent Core Web Vitals mainly because it is visited by users geographically close to the datacenter, equipped with fast connections and modern devices, is more vulnerable to a strong influx of visitors coming from completely different network conditions.
This scenario can occur naturally, for example following an international campaign, a piece of content going viral, or a sudden surge in traffic from a particular country. But it's also possible to imagine an adverse scenario in which someone uses standard traffic acquisition tools to intentionally generate a large amount of visits from markets where advertising costs are very low and average connectivity conditions are poor.
Buying advertising traffic is obviously a normal and legitimate activity in itself; whether it's intentionally used to harm a competitor is a different matter and may depend on the methods used, the advertising platforms' terms, and applicable regulations. The key question, from a Web Performance perspective, isn't how to implement such an operation, but rather understanding why a poorly optimized infrastructure might be more vulnerable to an artificial shift in its user mix.
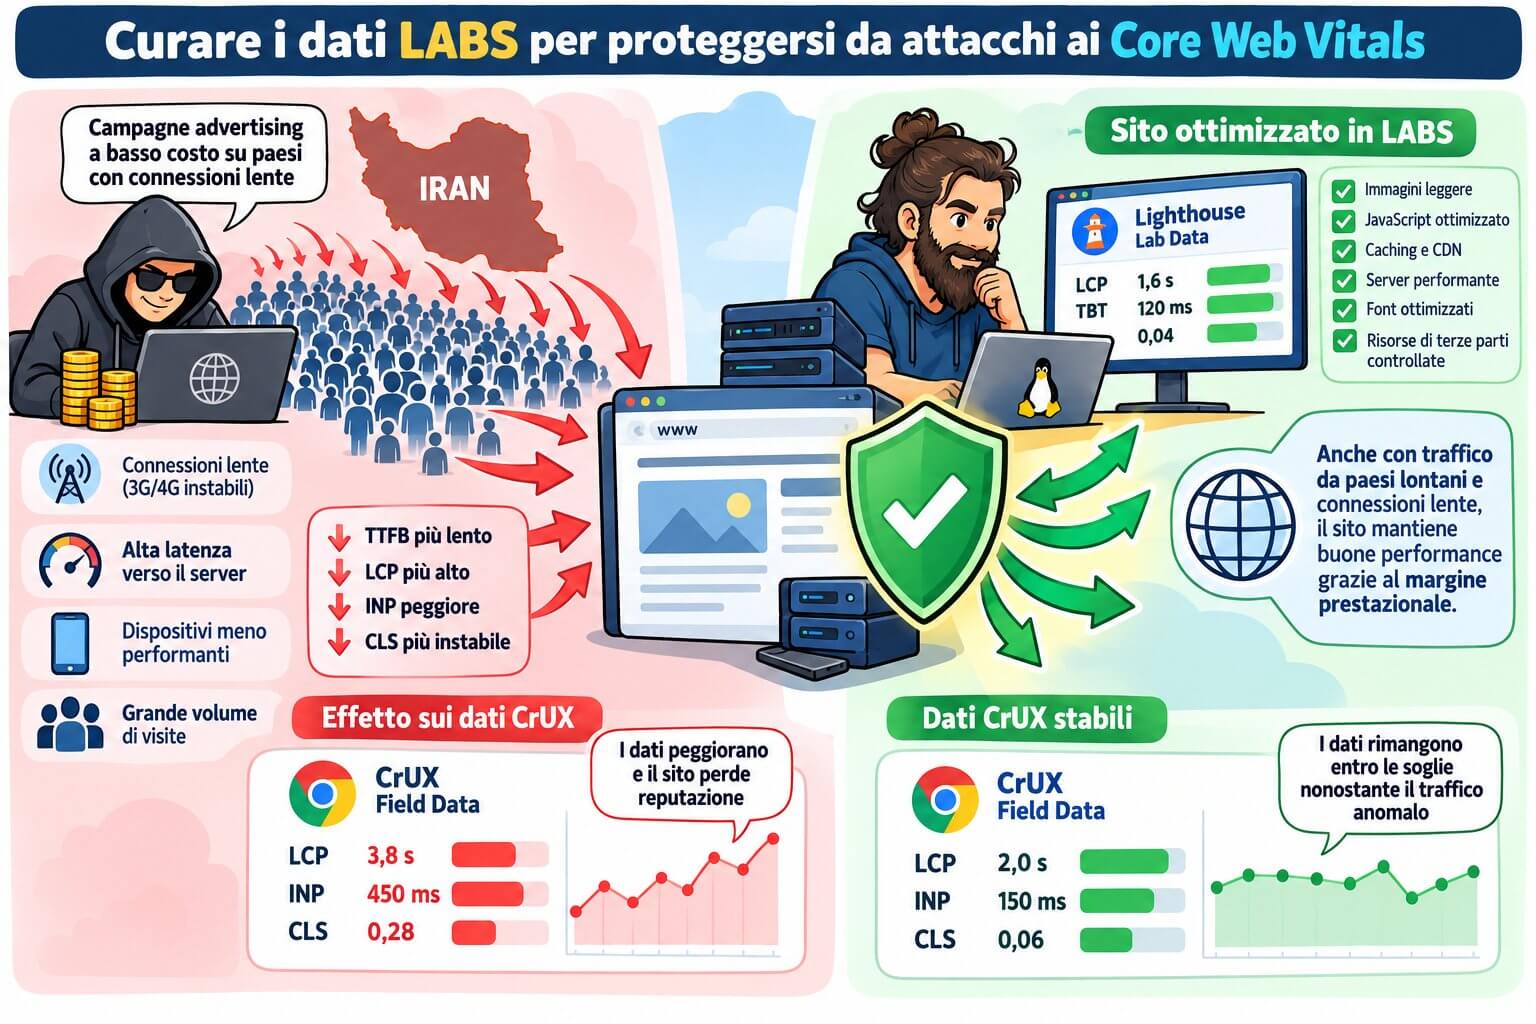
Imagine, for example, an Italian website hosted exclusively in Europe suddenly receiving a very high volume of visits from a geographically distant country, with higher latencies and a significant share of slower mobile connections. We might consider, for example, Iran or, more generally, markets where a significant portion of users navigate under significantly different network conditions than those of urban Italians.
These users may experience increased latency, slower downloads, and longer load times . The TTFB observed by the browser may also increase due to geographic distance and network latency, which may in turn delay the loading of resources required to display the LCP element.
Chrome UX Report doesn't use all page visits. Only a portion of Chrome users meet the criteria to contribute to the CrUX dataset. Furthermore, the metrics aren't calculated by taking a simple arithmetic average of all visits, but by analyzing a distribution and using the 75th percentile.
Therefore, there is no formula like "X slow visits equal Y lost points." Device, browser, user eligibility for CrUX, geographic distribution, amount of regular site traffic, and actual observed performance are all determining variables.
However, if a significant enough amount of new experiences actually enter the CrUX dataset and perform worse, the distribution of field data may change.
And this is where the topic of LABS data comes back to the fore.
A site that already has little margin in lab tests—for example, with an LCP close to the 2,5-second threshold in simulated conditions, hundreds of requests, excessive JavaScript, and very large images—is highly dependent on the quality of the network and the user's device. When those favorable conditions are removed, the risk of exceeding the thresholds increases rapidly.
Conversely, a site designed to achieve good LABS scores even under more demanding network and CPU scenarios has a sort of performance buffer. If latency increases by 100 or 200 milliseconds, if available bandwidth decreases, or if traffic suddenly arrives from less powerful devices, the site is more likely to remain within acceptable limits.
Curing LABS therefore also becomes a form of performance hardening.
This isn't to defend yourself from a phantom algorithm or to claim that negative SEO campaigns based on Core Web Vitals are always effective. There's no guarantee that such an attempt will produce a specific result, and Core Web Vitals represent only one of the many signals used by ranking systems.
Rather, it means avoiding building a site that works well only as long as the favorable statistical conditions of its audience remain unchanged.
If to get green Core Web Vitals you require almost all visitors to have fiber, 5G, recent smartphones, and low latency to your server, you haven't built a truly fast site: you've built a site that appears fast within a favorable scenario.
Serious optimization must instead aim to maintain a sufficient margin even when that scenario changes, regardless of whether the change is natural, due to an advertising campaign, international growth of the project or deliberately anomalous traffic.
Optimize for data or optimize for the user?
At the root of everything is a more general question.
Are we optimizing a number or are we optimizing a system?
If the goal becomes exclusively “exceeding the Core Web Vitals ”, it is easy to fall into the temptation of looking only at the data officially used for that evaluation.
Google itself, however, makes both real data from CrUX and laboratory data from Lighthouse available within PageSpeed Insights. These two sections aren't just randomly placed next to each other: one describes the aggregated real-world experience, the other helps diagnose performance issues.
CrUX data is therefore incredibly valuable and must play a central role in web performance analysis. But turning this centrality into the idea that everything related to LABS is irrelevant means losing one of the most useful tools for preventing problems, identifying regressions, and understanding the technical causes of poor performance.
CrUX and LABS should be read together
The final point is therefore simple.
You don't have to choose between CrUX and LABS.
You need to know the limitations and advantages of both.
CrUX tells us what happened to real users of our site, on the networks and devices they actually used. It's essential for understanding the quality of the real experience and represents the benchmark for field evaluation of Core Web Vitals.
LABS allows us to create controlled conditions, compare before and after an intervention, identify bottlenecks and verify how much performance margin a page actually has.
If your audience browses almost exclusively through lightning-fast connections and cutting-edge smartphones, CrUX data could be excellent even in the presence of significant inefficiencies.
This doesn't mean CrUX is wrong.
This means that CrUX is accurately describing the audience you have today.
The lab, on the other hand, can help you understand what might happen tomorrow, or what is already happening to that portion of users who have less favorable conditions.
The correct mindset for anyone who seriously deals with Web Performance must therefore be this: give maximum importance to real data without ever ceasing to observe the laboratory data.
Because a truly fast site isn’t simply a site that currently shows three green indicators in PageSpeed Insights.
It's a site designed to stay fast even when the network slows down, your device is less powerful, traffic increases, or operating conditions change.
And it is precisely in the union between field data, LAB data, application analysis and system optimization that we can distinguish simple score optimization from true performance optimization.
Eyes don't lie.
Ultimately, beyond PageSpeed Insights, Lighthouse, CrUX, and all the other analytics tools available, there's an incredibly simple way to understand how a site actually performs: by looking at it with your own eyes and using it in the real-world conditions in which users use it . Try browsing it on your smartphone in a crowded place, a pub, a restaurant, inside a building with poor cell phone coverage, or while on vacation in an area where mobile signal isn't particularly stable.
It's precisely in these situations that delays emerge, images appearing slowly, elements moving, interactions slow to respond, and pages that seemed lightning-fast in the office but, outside of a high-performance Wi-Fi network, reveal their limitations. Of course, the classic network throttling systems offered by browsers like Chrome are also very useful, allowing you to simulate slower connections and less powerful CPUs, but no simulation can completely replace direct experience.
Eyes don't lie : if a site seems slow when you actually use it, under less than ideal conditions, it's very likely that some of your users are having exactly the same experience. And this, ultimately, is the most concrete meaning of Web Performance: not just getting green numbers, but ensuring that the site actually appears and feels fast to those who use it.

